README.md 02_about.md
osa-con-2026 › README.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck README.md markdown utf-8 1:38 3% OSA Con 2026 · San Francisco Getting your agents to write (good) pipelines on Apache Spark Declarative pipelines, a Spark Connect sandbox, and context on your Spark version and your metrics.
Lisa N. Cao
Staff DevRel, Databricks
README.md 02_about.md 03_study_design.md
osa-con-2026 › 02_about.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck 02_about.md fast markdown utf-8 2:38 5%
About me Staff DevRel at Databricks, on the open source team Co-host of This Week in Open Lakehouse with Scott Haines, at openlakehouse.io Writes at systemsnull.net Latest posts: Apache Iceberg v4 Column Updates , Building a Spark Connect Client in OCaml , All About Iceberg's File Format API
LinkedIn
Apache Spark on YouTube
02_about.md 03_study_design.md 04_hallucination_classes.md
osa-con-2026 › 03_study_design.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck 03_study_design.md markdown utf-8 3:38 8%
The study 22 tasks × 12 seeded datasets × 2 arms = 528 runs Same ticket same data claude-opus-4-8 A: procedural PySpark no skill B: Declarative Pipelines pyspark-sdp skill No check Dry-run before any data Run Run Grade blind, on the output Both arms get feedback and can retry, up to a cap. The dry-run is part of what arm B is testing, so arm A doesn't get one.
03_study_design.md 04_hallucination_classes.md 05_ansi_defaults.sh
osa-con-2026 › 04_hallucination_classes.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck 04_hallucination_classes.md markdown utf-8 4:38 11%
API Hallucinations Type What the agent did What's actually true Signature Used a real method with the wrong arguments: dropDuplicatesWithinWatermark(["order_id"], "10 min") The method only takes the columns. The time window comes from withWatermark(). Method Called something that sounds right: broadcast_hint() No such method exists. The real one is F.broadcast(df). Platform Used Databricks APIs in open source Spark: @dlt.table, apply_cdc() They're real, but they're Lakeflow APIs and aren't in OSS 4.1. Version Used a pre-4.0 habit: F.col("amount").cast("double") The API is real, but from 4.0 ANSI mode makes it raise on a bad row. try_cast is the fix.
04_hallucination_classes.md 05_ansi_defaults.sh 06_log_signatures.md
osa-con-2026 › 05_ansi_defaults.sh
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
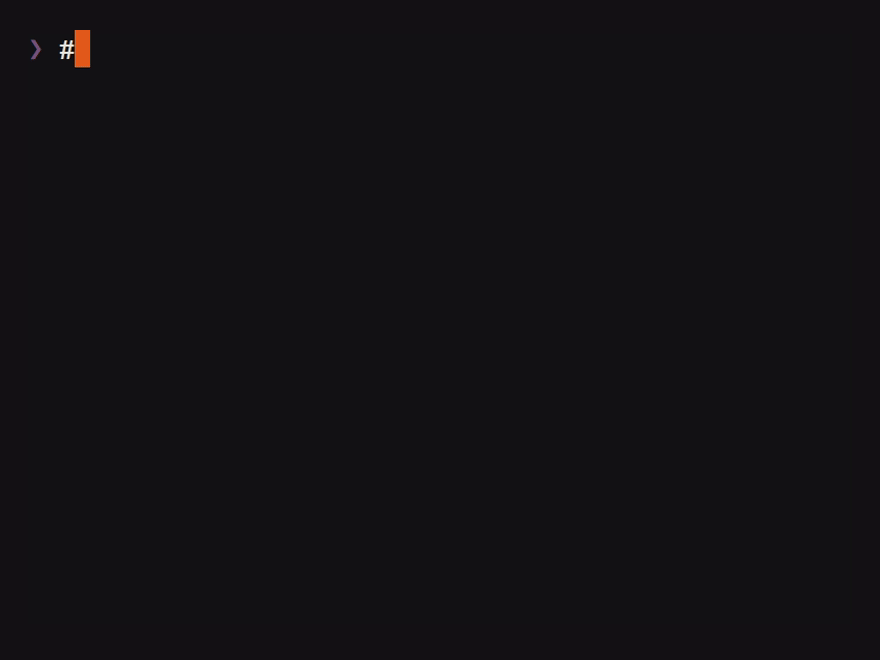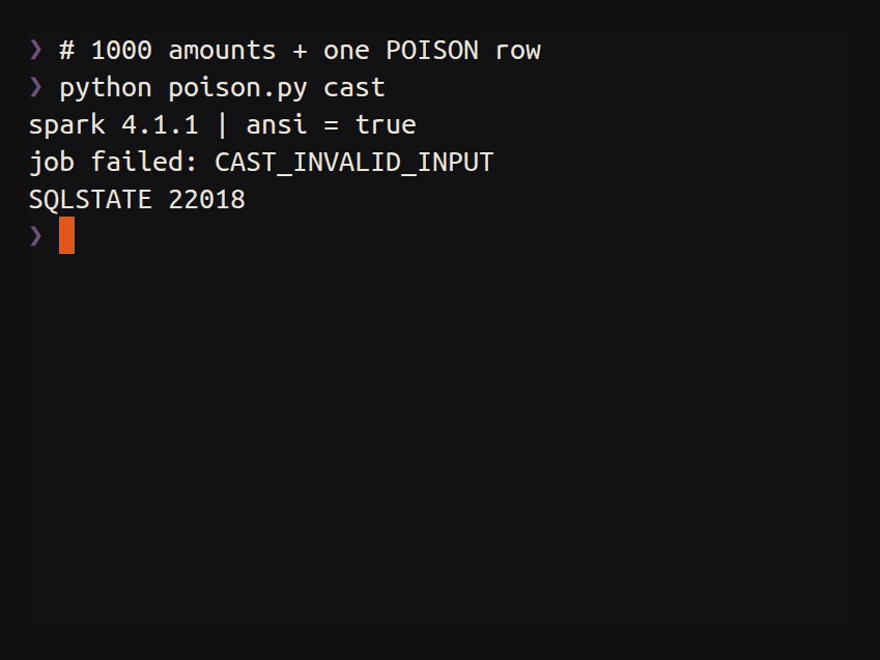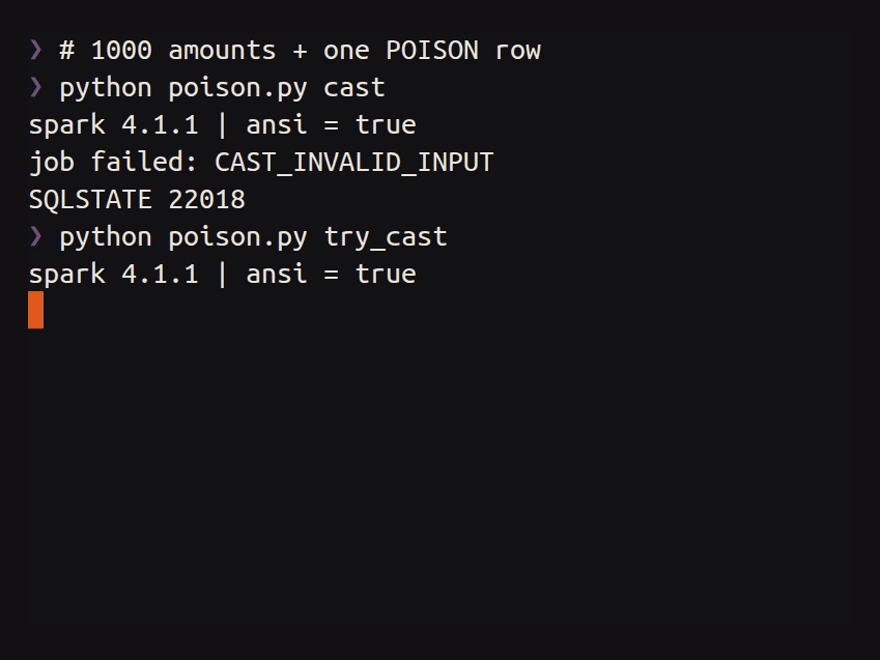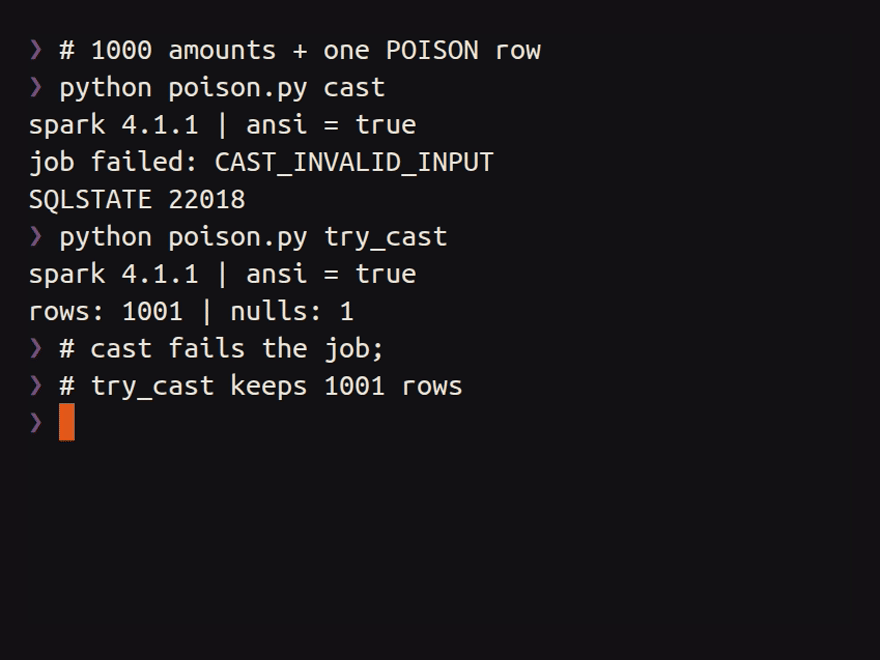
CORE osa-con-deck 05_ansi_defaults.sh shell utf-8 5:38 13% Pre-4.0 casts under ANSI mode spark.sql.ansi.enabled defaults to true from 4.0; the training data does not say which version an example targets.
python · spark 4.1.1 · ansi on
# 1000 valid rows + "POISON"
F.col("amount" ).cast("double" )
# CAST_INVALID_INPUT
# SQLSTATE: 22018
F.col("amount" ).try_cast("double" )
# 1001 rows, one null recording · ansi_poison
05_ansi_defaults.sh 06_log_signatures.md 07_failure_modes.md
osa-con-2026 › part-1 › 06_log_signatures.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-1/06_log_signatures.md markdown utf-8 6:38 16%
Pipeline-Level Hallucinations Error you see Plain meaning UNRESOLVED_COLUMNThe code uses a column that isn't there, because the agent made it up or it changed upstream. TABLE_OR_VIEW_NOT_FOUNDThe code reads a table nothing creates, like spark.read.table("upstream_that_nobody_wrote"). SESSION_MUTATION_IN_DECLARATIVE_PIPELINEThe agent called spark.conf.set inside a pipeline. CANNOT_MODIFY_CONFIGA setting that can't be changed at runtime, like spark.jars, was set in the pipeline spec. Python exception at registration The code failed as Spark loaded it, usually from the wrong arguments or a made-up method. Successful run, incorrect values There's no error at all.
06_log_signatures.md 07_failure_modes.md 08_corpus.md
osa-con-2026 › 07_failure_modes.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck 07_failure_modes.md dwell markdown utf-8 7:38 18%
Silent Errors What happened What went wrong A currency dropped during a join Rows with no currency match fell out of the join, so they never reached the sum. A day boundary in the wrong timezone Timestamps were bucketed in the wrong zone, so rows near midnight landed on the wrong day. A nondeterministic dedup With no deterministic tie-break, dedup could keep different rows each run, so counts changed. A predicate that removed rows A filter also matched valid rows, and dropped them without an error.
You only catch these by comparing the output to a trusted number from outside the pipeline. Nothing in the pipeline reports them.
07_failure_modes.md 08_corpus.md 09_four_checks.md
osa-con-2026 › 08_corpus.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck 08_corpus.md dwell markdown utf-8 8:38 21%
Spark Corpus Considerations Public Spark material skews to tutorials Production code sits in private repositories and internal wikis 2.x, 3.x and 4.x material arrives without a version marker The 4.1 docs are not in the loop unless something puts them there Example: ANSI is on by default from 4.0, so a pre-4.0 cast now raises on a bad row !
Observation
The corpus distribution claim is practitioner observation, not measurement.
08_corpus.md 09_four_checks.md 10_the_argument.md
osa-con-2026 › 09_four_checks.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck 09_four_checks.md dwell markdown utf-8 9:38 24%
A Spark Harness Check Question When it fails What addresses it Evidence API Real, current, the right method? Usually raises Dry-run, skill Invented APIs and pre-4.0 casts; 55 of 264 builds stopped before any output Performance Concise and efficient? Passes, slow SDP's bounds, skill Python loops in 246 of 255 programs vs 47 of 258; collect 42 vs 0; 134 vs 68 lines; UDF on the classifier task 12 of 12 vs 7 of 12 Scope Limited to what it should touch? Blocked if enforced Connect, catalog, SDP No sparkContext or _jvm on the client; sandbox_<id> per agent; SDP refuses spark.conf.set in a query function Correctness Does it answer the question? Passes, wrong Skill, metric views, a trusted number Silent errors appear in both; timezone errors 7 → 0; MEASURE() 0.0923 vs 0.2384 by hand
Performance counts are procedural vs declarative. Scope is by design, not measured by the study. Dedup and row-drop errors moved with neither the skill nor the framework.
09_four_checks.md 10_the_argument.md 11_failure_path.md
osa-con-2026 › 10_the_argument.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck 10_the_argument.md dwell markdown utf-8 10:38 26%
Harness Benefits What the harness does Built with Declare bounds how the agent writes pipelines, checked by dry-run before any data is read Declarative Pipelines, 4.1 Scope runs the agent against a local Connect server, writing only to its own namespace Spark Connect, 4.2; Feather, 4.3 Context gives the agent the idioms of the Spark version you run, and what your metrics mean a skill pinned to 4.1+; metric views, 4.2
10_the_argument.md 11_failure_path.md part-1/README.md
osa-con-2026 › 11_failure_path.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck 11_failure_path.md dwell markdown utf-8 11:38 29%
Agent writes spec + transforms Dry-run no cluster, no data Connect + catalog no JVM, own namespace Run executors Output tables, dashboards Context skill, metric views before it writes Declare invented methods, broken graph Scope config, production tables, if enforced Performance loops, collect, UDFs: passes, at a cost Correctness nothing raises: wrong data $ $$$ 11_failure_path.md README.md 13_dry_run_path.md
osa-con-2026 › part-1 › README.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-1/README.md fast markdown utf-8 12:38 32% ❯ git switch part-1Declare Let Spark check the pipeline before it runs
part-1/README.md 13_dry_run_path.md 14_sdp_code.py
osa-con-2026 › part-1 › 13_dry_run_path.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-1/13_dry_run_path.md dwell markdown utf-8 13:38 34%
YOU DECLARE @dp.materialized_view def silver_orders(): ... @dp.materialized_view def gold_daily_revenue(): ... SPARK WORKS OUT source silver gold the run order from the dependencies the checks before any data spark-pipelines dry-run --spec create_dataflow_graph register_definitions imports, decorators start_run(dry=True) resolve + validate verdict COMPLETED | 42P01 never reached: executors, source data, table writes 13_dry_run_path.md 14_sdp_code.py 15_dry_run.sh
osa-con-2026 › part-1 › 14_sdp_code.py
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-1/14_sdp_code.py dwell python utf-8 14:38 37%
python · one_file.py
spark = (SparkSession.builder.appName("orders" )
.config("spark.sql.session.timeZone" , "UTC" )
.getOrCreate())
spark.sparkContext.setLogLevel("WARN" )
SCHEMA = "order_id string, amount double, event_time string"
bronze = spark.read.text("file:///tmp/osa-demo/orders.ndjson" )
bronze.write.mode("overwrite" ).saveAsTable("bronze_orders" )
silver = (spark.read.table("bronze_orders" )
.select(F.from_json("value" , SCHEMA).alias("o" ))
.select("o.order_id" , "o.amount" , "o.event_time" )
.where(F.col("order_id" ).isNotNull()))
silver.write.mode("overwrite" ).saveAsTable("silver_orders" )
gold = (spark.read.table("silver_orders" )
.groupBy(F.col("event_time" ).try_cast("date" ).alias("day" ))
.agg(F.sum("amount" ).alias("revenue" )))
gold.write.mode("overwrite" ).saveAsTable("gold_daily_revenue" )
spark.stop() python · transformations/bronze.py
@dp.materialized_view
def bronze_orders():
return spark.read.text("file:///tmp/osa-demo/orders.ndjson" ) python · transformations/silver.py
@dp.materialized_view
def silver_orders():
return (spark.read.table("bronze_orders" )
.select(F.from_json("value" , SCHEMA).alias("o" ))
.select("o.order_id" , "o.amount" , "o.event_time" )
.where(F.col("order_id" ).isNotNull())) python · transformations/gold.py
@dp.materialized_view
def gold_daily_revenue():
return (spark.read.table("silver_orders" )
.groupBy(F.col("event_time" ).try_cast("date" ).alias("day" ))
.agg(F.sum("amount" ).alias("revenue" ))) 14_sdp_code.py 15_dry_run.sh 16_interception.md
osa-con-2026 › part-1 › 15_dry_run.sh
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-1/15_dry_run.sh dwell shell utf-8 15:38 39%
Dry-run: error, fix, run recording · spark-pipelines · spark 4.2.1
15_dry_run.sh 16_interception.md 17_bounded_agent.md
osa-con-2026 › part-1 › 16_interception.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-1/16_interception.md markdown utf-8 16:38 42%
Stopping hallucinations before the run Procedural Declarative (SDP) Errors stopped before any output none 55 of 264 builds Where errors surface mid-run, sometimes after partial writes at the dry-run Cluster time on a failed run up to about 521 executor-seconds about 0.5 executor-seconds Cluster time overall about 34x higher baseline
From Built for Agents: The Case for Spark Declarative Pipelines .
16_interception.md 17_bounded_agent.md 18_dry_run_limits.py
osa-con-2026 › part-1 › 17_bounded_agent.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-1/17_bounded_agent.md dwell markdown utf-8 17:38 45% Agents with and without SDP Counted from the final programs of 528 runs.
Final programs Procedural Declarative (SDP) Mean lines 134.0 67.9 Contain a Python loop 246 of 255 47 of 258 Call collect or toPandas 42 0 Rebuild a DataFrame in a loop 18 0 Run a Spark action in a loop 7 0 Classifier task: use a Python UDF 12 of 12 7 of 12
17_bounded_agent.md 18_dry_run_limits.py part-2/README.md
osa-con-2026 › part-1 › 18_dry_run_limits.py
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-1/18_dry_run_limits.py dwell python utf-8 18:38 47%
What dry-run misses python · streaming dedup
@dp.table
def deduped():
# no withWatermark()
return (spark.readStream
.table("events" )
.dropDuplicates(["id" ]))
# dry-run: COMPLETED
# unbounded state python · epoch units
# ms epoch typed as seconds
F.col("ts" ).cast("timestamp" )
# dry-run: COMPLETED
# run: COMPLETED
# dates near year 58437
# no error raised Dry-run checks structure and configuration, not whether the answer is right. Wrong values still get through, and scope only limits where they land.
18_dry_run_limits.py README.md 20_plan_as_unit.md
osa-con-2026 › part-2 › README.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-2/README.md fast markdown utf-8 19:38 50% ❯ git switch part-2Scope Develop against Spark Connect, locally and cheaply
part-2/README.md 20_plan_as_unit.md 21_unsupported_surface.py
osa-con-2026 › part-2 › 20_plan_as_unit.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-2/20_plan_as_unit.md dwell markdown utf-8 20:38 53%
How a Connect client talks to the server CLIENT DataFrame calls pyspark-client, no JVM unresolved plan names not checked SPARK CONNECT SERVER analyzer catalog lookup Catalyst optimize, plan execution driver + executors plan, protobuf over gRPC Arrow batches pyspark-client is a 1.7 MB download. pyspark, with the JVM jars, is 450 MB.
20_plan_as_unit.md 21_unsupported_surface.py 22_catalog_authority.md
osa-con-2026 › part-2 › 21_unsupported_surface.py
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-2/21_unsupported_surface.py python utf-8 21:38 55%
What a Connect client can't do python · pyspark-client 4.2.0
# surface.py
spark = (SparkSession.builder
.remote("sc://localhost:15002" ).getOrCreate())
spark.sparkContext
spark.range(3 ).rdd
SparkSession.builder.remote("sc://localhost:15002" ) \
.enableHiveSupport().getOrCreate()the output
sparkContext -> JVM_ATTRIBUTE_NOT_SUPPORTED
df.rdd -> JVM_ATTRIBUTE_NOT_SUPPORTED
enableHiveSupport() -> no error
catalog: in -memory Also refused: _jvm, _jsc, setLogLevel, addPyFile, accumulators. enableHiveSupport() is the quiet one: it only warns.
21_unsupported_surface.py 22_catalog_authority.md 23_local_and_prod.md
osa-con-2026 › part-2 › 22_catalog_authority.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-2/22_catalog_authority.md markdown utf-8 22:38 58% One namespace per agent Privileges come from the catalog; identity comes from the connection string.
Principal Privilege Each agent READ per policyEach agent, in its namespace CREATE, MODIFY on sandbox_<id>Each agent, against production none
text · identity rides the connection string
sc://host:15002 /
;user_id=agent-7
;token=...
;use_ssl=true 22_catalog_authority.md 23_local_and_prod.md 24_local_to_cluster.sh
osa-con-2026 › part-2 › 23_local_and_prod.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-2/23_local_and_prod.md dwell markdown utf-8 23:38 61%
Local to production bash · same client code, one value changes
# on the laptop (needs a Spark distribution; pip pyspark has no sbin/)
$SPARK_HOME/sbin/start-connect-server.sh

SPARK_REMOTE="sc://localhost:15002"                               # development
SPARK_REMOTE="sc://spark-connect.spark.svc.cluster.local:15002"   # production
Each agent writes to its own sandbox_<id> namespace, with no privileges on production spark-pipelines ignores SPARK_REMOTE; point it at a server with --remote (tested on 4.2.1)Project Feather, merged for Spark 4.3, targets interactive execution for small data on one machine 23_local_and_prod.md 24_local_to_cluster.sh 25_feather.md
osa-con-2026 › part-2 › 24_local_to_cluster.sh
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-2/24_local_to_cluster.sh dwell shell utf-8 24:38 63%
Same script, one value changed recording · the second run is a Connect server on this laptop, standing in for your cluster
24_local_to_cluster.sh 25_feather.md part-3/README.md
osa-con-2026 › part-2 › 25_feather.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-2/25_feather.md dwell markdown utf-8 25:38 66%
Small runs, fixed overhead, and Project Feather Below about 100 MB, planning, scheduling and serialization outweigh the data A dry-run takes about 7.9 s, mostly JVM startup Feather Proposal SPARK-56978, passed a community voteStatus merged for Spark 4.3 Objective interactive execution for small data on one machine
!
Reasoning, not measurement
Shorter local loops allow more attempts before a cluster is needed. Feather is also absent from the corpus, and a local mode that diverges from cluster behavior is a new silent surface.
25_feather.md README.md 27_skill_structure.py
osa-con-2026 › part-3 › README.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-3/README.md fast markdown utf-8 26:38 68% ❯ git switch part-3Context Writing down what the model does not know
part-3/README.md 27_skill_structure.py 28_skill_swap.md
osa-con-2026 › part-3 › 27_skill_structure.py
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-3/27_skill_structure.py python utf-8 27:38 71%
Inside the pyspark-sdp skill Attribute Value Path .claude/skills/pyspark-sdp/Size 164 lines Scope OSS Spark 4.1 and later Content declare a view, wire a dependency, write a valid spec Excluded what the pipeline should compute
pyspark-sdp/SKILL.md · excerpt
import dlt # WRONG: no such module
# RIGHT: OSS SDP
from pyspark import pipelines as dp
@dp.materialized_view(name="ds" )
def ds():
return SparkSession.active().range(3 )An earlier spark-safety skill moved the silent-defect rate by 0.000 and was removed.
27_skill_structure.py 28_skill_swap.md 29_metric_views.py
osa-con-2026 › part-3 › 28_skill_swap.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-3/28_skill_swap.md dwell markdown utf-8 28:38 74% Timezone errors and the skill new_stream_stream_join, seed 16180: same task, same seed, both runs exit 0.
python · before, condensed
# frozen skill
ts = F.to_timestamp("event_time" ) # session timezone
# tz-independent UTC calendar day
day = F.floor(F.unix_timestamp(ts) / 86400 )python · after, condensed
# skill with the UTC idiom
ts = F.to_timestamp(tagged)           # naive strings get a Z
day = F.to_date(F.to_utc_timestamp(ts, F.current_timezone()))
Day (June) Correct Before After 20 996 735 996 21 1,003 1,000 1,003 22 1,014 1,000 1,014 23 987 1,021 987 24 0 244 0
Payments per settlement day. In the re-run, timezone errors went 7 → 0, and six of those seven runs still shipped a row-drop error.
28_skill_swap.md 29_metric_views.py 30_metric_view_agent.md
osa-con-2026 › part-3 › 29_metric_views.py
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-3/29_metric_views.py dwell python utf-8 29:38 76%
Metric views yaml · delivery_metrics
source : default.sessions
dimensions :
- name : region
expr : region
measures :
- name : conversion_rate
expr : SUM(CAST(converted AS INT)) / COUNT(1 )
- name : active_users
expr : COUNT(DISTINCT user_id)June By hand MEASURE()Conversion rate 0.2384 0.0923 Active users 69,420 9,994
The by-hand answers average regional rates and sum daily distinct counts. Both exit 0.
29_metric_views.py 30_metric_view_agent.md 31_before_and_after.py
osa-con-2026 › part-3 › 30_metric_view_agent.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-3/30_metric_view_agent.md dwell markdown utf-8 30:38 79%
The same questions, with and without the metric view Question Statements, metric view Statements, raw tables Conversion rate in June, by region 2 6 Users active in June 2 2 AOV and revenue per paying user, core regions on weekends 1 8
In the raw-tables run of the third question, the agent found the metric view in the catalog to learn what "core" means.
30_metric_view_agent.md 31_before_and_after.py 32_metric_view_film.sh
osa-con-2026 › 31_before_and_after.py
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck 31_before_and_after.py dwell python utf-8 31:38 82%
The same daily table, before and after python · before, excerpt
spark = (SparkSession.builder
.master("local[*]" ).getOrCreate())
for c in df.columns: # one job per column
df.filter(F.col(c).isNotNull()).count()
currencies = [r[0 ] for r in
df.select("currency" ).distinct().collect()]
@F.udf(returnType=DoubleType())
def clean_amount(v): ...
spark.conf.set("spark.sql.shuffle.partitions" , "8" )
for cur in currencies: # rebuild per currency
... python · after, excerpt
@dp.materialized_view
def daily_payments():
return (spark.read.json(PAYMENTS)
.withColumn("amount" ,
F.col("amount" ).try_cast("double" )))
@dp.materialized_view
def daily_revenue():
return spark.sql(
"SELECT day, MEASURE(revenue) AS revenue "
"FROM payment_metrics GROUP BY day" ) the server is one flag
$ spark-pipelines --remote sc://your-cluster:15002 run Illustrative, from patterns in the recorded runs. Each piece ran on Spark 4.2.1, but not this exact program.
31_before_and_after.py 32_metric_view_film.sh 33_close.md
osa-con-2026 › part-3 › 32_metric_view_film.sh
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-3/32_metric_view_film.sh dwell shell utf-8 32:38 84%
An agent finding a metric view real Claude Code session · claude-opus-4-8 · spark 4.2.1
32_metric_view_film.sh 33_close.md 34_resources.md
osa-con-2026 › 33_close.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck 33_close.md dwell markdown utf-8 33:38 87%
What to try this week What it does Try this week Declare bounds what the agent writes; dry-run checks the graph, not the values dry-run one pipeline before you run it Scope a Connect server decides what the agent can reach; the code stays the same point your agent at sc://localhost:15002 Context a skill for your version, metric views for your definitions one idiom in a skill, one metric in a view
Dry-run checks structure and scope limits damage. What the agent needs to know about your version and your metrics, you have to give it.
33_close.md 34_resources.md appendix/README.md
osa-con-2026 › 34_resources.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck 34_resources.md fast markdown utf-8 34:38 89%
Thank you Resource Location Slides systemsnull.net/talks/osa-con-2026/deckDemos github.com/lisancao/spark-demosMetric views spark-demos/demos/01_metrics_viewsStudy open-lakehouse/safe-spark-agents-paperBlog Built for Agents: The Case for Spark Declarative Pipelines Skill lisancao/pyspark-sdpConnect gotchas spark.apache.org/docs/latest/spark-connect-gotchas.htmlFeather SPARK-56978
34_resources.md README.md 36_a1_versions.md
osa-con-2026 › appendix › README.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck appendix/README.md fast markdown utf-8 35:38 92% ❯ git switch appendix
Appendix
appendix/README.md 36_a1_versions.md 37_cluster_compute.md
osa-con-2026 › appendix › 36_a1_versions.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
APPX osa-con-deck appendix/36_a1_versions.md markdown utf-8 36:38 95%
Version anchors Subject Version Study results OSS Spark 4.1 SDP availability 4.1 Connect plan, protocol, behavior 4.2.0 Metric views 4.2.0 Feather 4.3, merged Arrow on by default for Python UDFs 4.2 spark.sql.ansi.enabled default true4.x
36_a1_versions.md 37_cluster_compute.md 38_authoring_cost.md
osa-con-2026 › part-2 › 37_cluster_compute.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-2/37_cluster_compute.md markdown utf-8 37:38 97%
Executor time by arm (a separate EKS sweep) Arm Executor-seconds Cost A, bare procedural 596 $0.032 B, declarative 17 $0.0009
~34×
total compute, A over B
!
Provenance
A separate 48-cell sweep on EKS, not the 528-run study. The $5,000 a month figure at 1,000 pipelines a week is a projection, and the sign reverses for small pipelines.
37_cluster_compute.md 38_authoring_cost.md
osa-con-2026 › part-2 › 38_authoring_cost.md
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18
CORE osa-con-deck part-2/38_authoring_cost.md markdown utf-8 38:38 100%
Code size and tokens, by arm Metric Arm B Arm A A minus B Final program lines 67.9 134.0 +66.1, CI [+61.9, +70.4] AST nodes 614.9 1105.5 +490.6, CI [+453, +530] Median tokens to correct 26,480 11,524 about 2.3× Completion 65.2% 68.9% 3.7 points to A