Apache Spark, the open lakehouse, and building AI systems that hold up in production.
Data Engineering / AI
12 items under this folder.
 Nov 05, 2026SD 2026.309The Ultimate Guide to Apache Spark 4.3Everything new in Apache Spark 4.3 and full feature breakdowns for stateful Real-time Mode, SCD Type 2 in Auto CDC, Project Feather, Spark Connect operation IDs and REST endpoints, DataFrame.zip and…
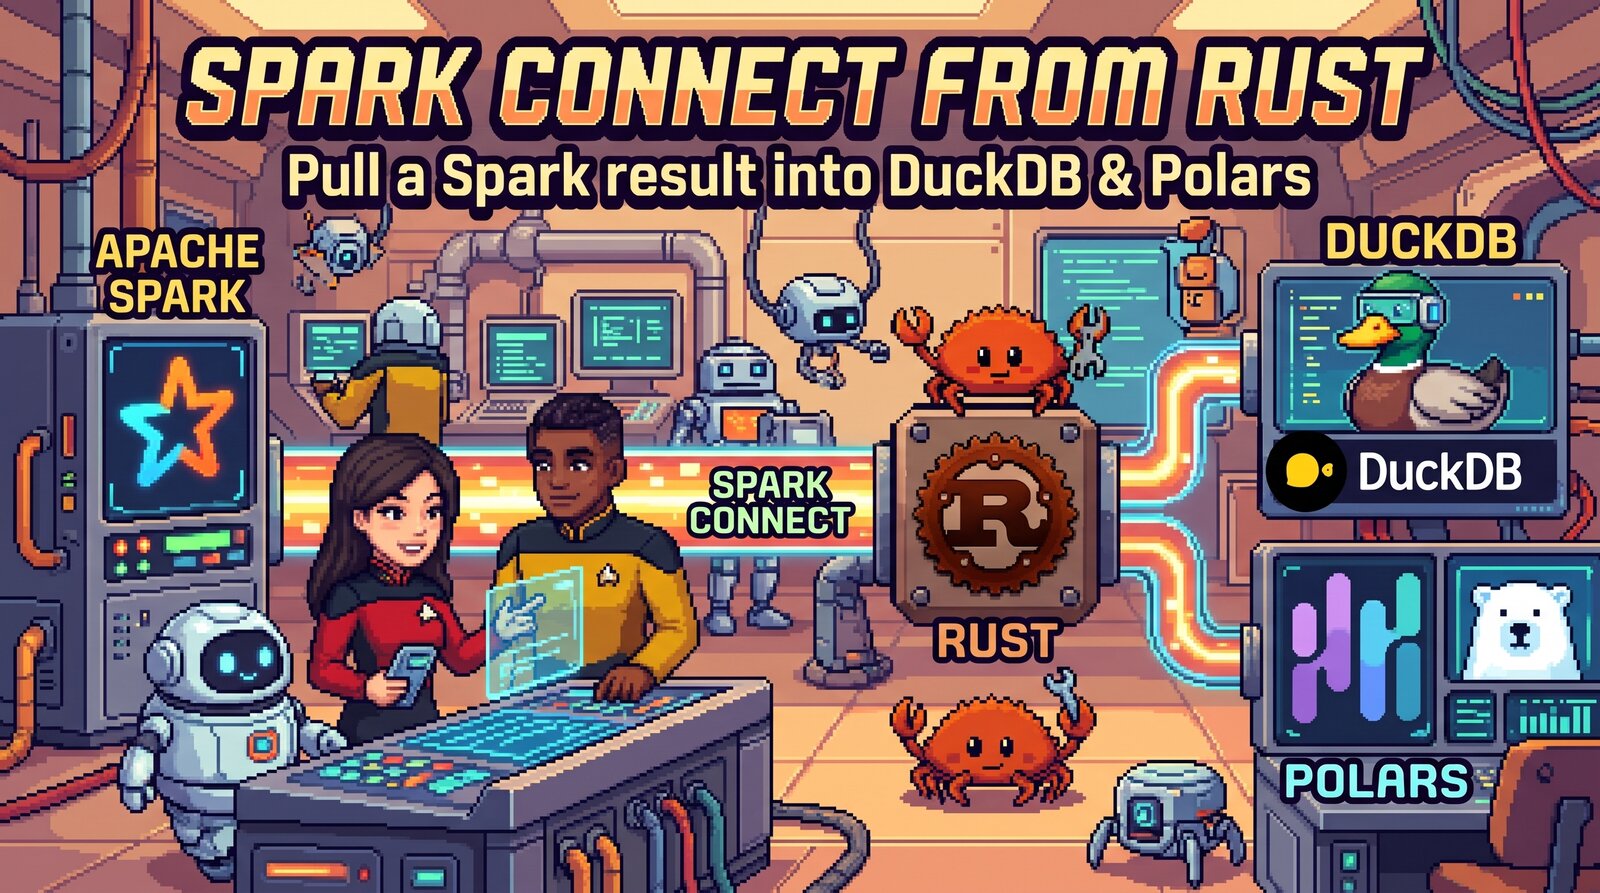 Nov 03, 2026SD 2026.307Spark Connect from Rust: Pull Spark outputs into DuckDB and PolarsA guide to using the Apache Spark Connect client for Rust to integrate spark with DuckDB and Polars: start a Spark 4.2 server, get a result out as Arrow, hand it to DuckDB 2.0 for an ASOF join and…
 Oct 27, 2026SD 2026.300Apache Iceberg v4 Column Updates Are About to Change Feature EngineeringIceberg v4 is adding column files, companion files that can hold one or more whole columns for every row of a data file and be swapped in by position at read time. This post explains why that…
 Oct 17, 2026SD 2026.290Building a Spark Connect Client in OCamlHow to build a Spark Connect client from the protocol up, in OCaml: compile the spark/connect protos, speak gRPC over HTTP/2 (ExecutePlan, AnalyzePlan, grpc-status-details-bin), build Relation and…
 Oct 12, 2026SD 2026.285All About Iceberg's File Format API: simplifying the engine/format interface and Parquet's multimodal futureApache Iceberg's File Format API (1.11, 1.12) explained with a runnable Java program: FormatModelRegistry keyed on the closed FileFormat enum (Parquet, Avro, ORC) and an open set of engine row types…
 Oct 05, 2026SD 2026.278An Idiot's Guide to Spark Connect ClientsEverything you need to go from "what is Spark?" to running jobs on a Spark Connect server from Python, Scala, Go, Rust or Swift, and working out what went wrong when it doesn't work.
 Oct 01, 2026SD 2026.274TUTORIAL: How to Build an Open Lakehouse on Your LaptopA self-contained tutorial that builds a complete open lakehouse in an empty folder, one layer at a time, from S3-compatible storage and Delta tables through Unity Catalog, Iceberg readers…
- Sep 29, 2026SD 2026.272Hosting an Entire Open Lakehouse on Port 8080Building lakehouse-at-home, a desktop stack for testing new Apache Spark and Iceberg releases before demoing them: Spark 4.0 and 4.1 side by side in Docker, Iceberg JDBC catalog on Postgres…
 Sep 28, 2026SD 2026.271From Pickle to Arrow: A Decade of Moving Data Between Spark's JVM and PythonHow Apache Arrow replaced pickle at every JVM-to-Python boundary in PySpark, from toPandas() in Spark 2.3 to pandas UDFs, mapInArrow, applyInArrow, Spark Connect, Arrow-optimized Python UDFs…
 Sep 28, 2026SD 2026.271AUTO_CDC: Turning an event log into current state with Spark Declarative PipelinesAUTO CDC (create_auto_cdc_flow) in Apache Spark 4.2 Declarative Pipelines, tested on messy data: SCD Type 1, keys, sequence_by, apply_as_deletes, out-of-order and stale events, and which targets…
 Sep 28, 2026SD 2026.271Stop Blaming Serialization for Slow Python UDFsSpark uses the word Arrow for a pandas conversion setting, a UDF transport and operator, and a data type your function receives. The difference between them is most of the difference in UDF…
 Sep 28, 2026SD 2026.271Most PySpark Tuning Advice Starts in the Wrong PlacePySpark runs DataFrame code in the JVM at native speed, and almost everything that makes it slow happens where data crosses into Python. Ordered by how much each one bought in my own measurements…